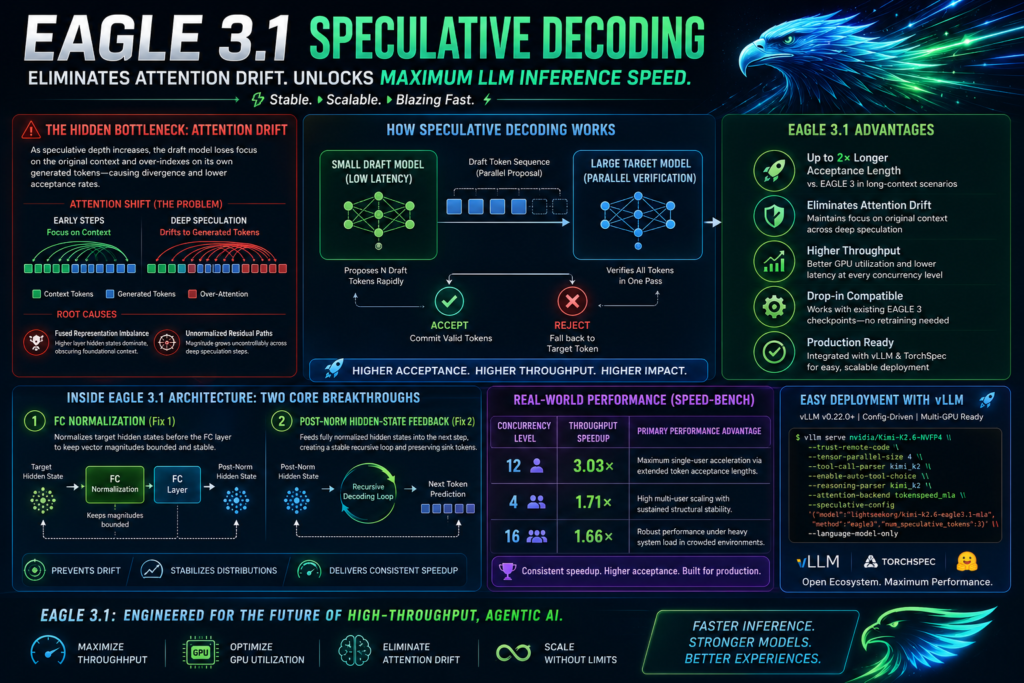
Optimizing LLM Inference Speed Up: How the EAGLE 3.1 Speculative Decoding Algorithm Eliminates Attention Drift
To maximize large language model throughput, engineering teams rely on a speculative decoding algorithm to accelerate generation speeds by validating […]